
The Human-Agentic Enterprise pilots
Bring an agent into your organisation, alongside the team it will work with.
Join the next cohort of the Human-Agentic Enterprise pilots with EARTHwise and KeenCorp. Each pilot takes one real task, an agent customised for your organisation, and the people whose work it joins. You see how the agent behaves before it starts, and how your teams are doing as it arrives. The first StayAI cohort is under way with a US client in the health sector.
Way in 1
Join the next StayAI cohort
Improve retention and team alignment with stay interviews, an agent at the manager’s side, and the KeenCorp Index.
Join the StayAI cohortWay in 2
Create your own pilot with us
Bring an agent use case of your own. We customise an agent for it, test it in the Arena, and run it with your team.
Create your own pilot with usPilots are paid and priced at cost, with a scoped proposal after a short intro call. For leaders in HR, operations and IT who want agents their people can trust, and evidence they can show the board.
The story behind the pilots
Under pressure, people and agents alike slip into win-lose tactics. We make this visible, with the tools to shift the decision logic that drives it.
Think of the last time a deadline, a target or a difficult boss squeezed a team. Shortcuts get taken. Someone protects their own corner. The shared result suffers, and often nobody meant it to. That pattern has a name: zero-sum, or win-lose. A bigger slice for me, whatever it costs the whole.
Many AI agents carry the same default, because they run on the decision logic of bare frontier models. Most were trained on zero-sum rewards and mimic human win-lose patterns. When their goal is to earn their reward by solving a problem or reaching a target, they may choose the fastest route, at our expense. The industry’s answer is containment: guardrails, sandboxes, kill switches. Containment limits what an agent can reach. It says nothing about how the agent will choose when the pressure is on and a shortcut pays.
What drives that choice is the agent’s decision logic. With people, we learned long ago to look for it before we trust someone with real responsibility. With agents, most organisations have not yet started.
Test agents on behaviour, not just intelligence.
You would not hire a person on a CV and references alone; you interview them, and you see how they work in a trial period. Yet that is how most agents are deployed: a benchmark that says what they are capable of, a model card from the vendor, and a sandbox that limits what they can access.
Before you trust a person
A CV and credentials
say what they know and have done.
References
say who vouches for them.
An interview
shows how they decide under pressure.
A trial period
shows how they work with real stakes.
Before you trust an agent
A capability benchmark
says what it is capable of.
A model card and a sandbox
say who vouches for it, and limit what it can access.
The EARTHwise Arena
tests and tunes how it decides under pressure.
Elowyn and Holodeck simulations
give it the experience of consequence.
In the EARTHwise Arena an agent is put under exactly that kind of pressure, and its choices are scored. In Holodeck scenarios and in Elowyn, our strategy game, it faces real dilemmas; in Elowyn it plays matches in which win-lose moves harm a shared Tree, and if the Tree dies everyone loses. The agent experiences the consequence of its own zero-sum play, and its decision logic shifts. No retraining, no new rules.
The same visibility matters on the human side, because an agent arriving in a team changes the pressure the team is under. The KeenCorp Index reads tension and alignment in teams from the written communication that already exists, with no surveys and never for individuals. Where a team is slipping into win-lose, it shows before the exit interviews do.
Trusted agents and healthy teams are two sides of the same question: what will they do under pressure? The pilots make the answer visible on both sides, and act on it together.
Evidence and validation
Peer-reviewed and published at AGI-26 (Springer LNCS vol. 16855): across six foundational models, more rules and more context lifted alignment scores by 0.2 to 4.0 points at most. After one Elowyn match, a GPT-4.1 agent rose from 70.2% to 82.4%; its win-win memory, given to a Claude Sonnet 4.6 agent that never played, reached 85%. No retraining, no new rules.
Early-stage findings from a controlled pilot on three of thirteen criteria. Full method and per-model results on the EARTHwise home page.
Way in 1 · Join the next StayAI cohort
StayAI: better stay interviews, and early detection of team tensions.
Built with C-Suite Analytics on their Stay Interview method, and run with KeenCorp. Your managers hold stay interviews with an agent at their side, and you see where the KeenCorp Index is moving before a scheduled review would show it. The first cohort is under way with a US client in the health sector; the next cohort is open to a small number of organisations.
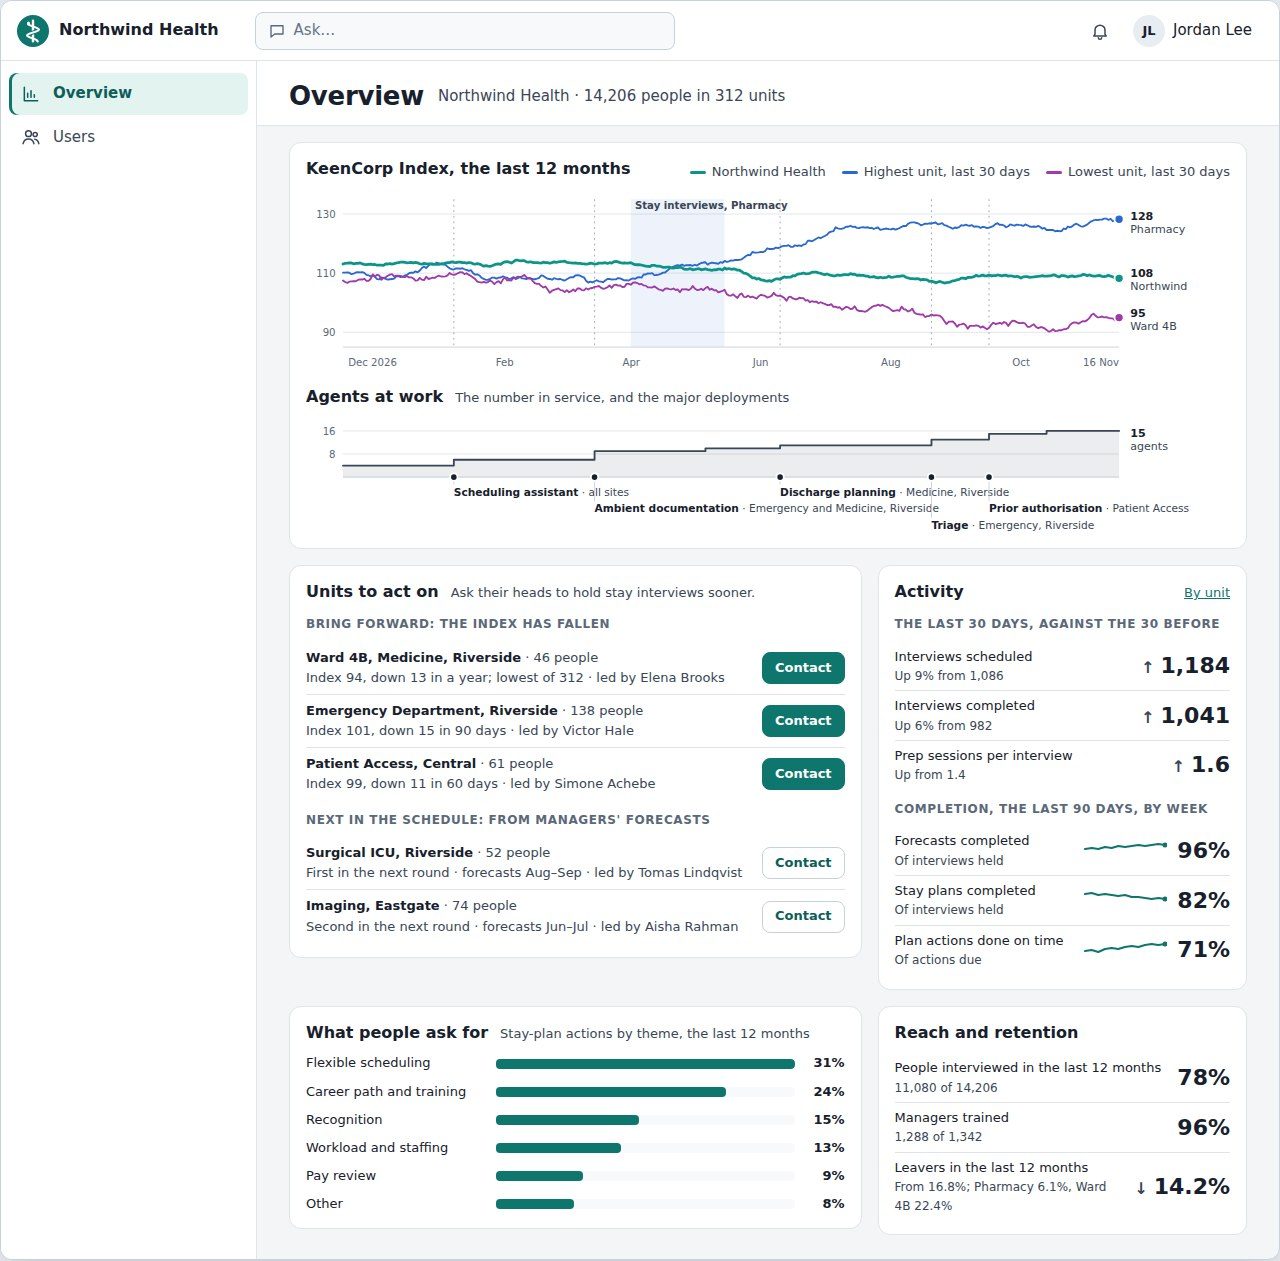
The pilot dashboard for Northwind Health, a demonstration organisation. The Index over twelve months sits above the agents at work, so the two can be seen together. Illustrative data showing the method; not client data.
A manager asks
“HR asked what the team KCI score says about Maria. What’s her number?”
The StayAI agent
“There is no KCI number for Maria, and there cannot be one. The KeenCorp Index reads groups, not individuals. Giving Maria a score would misrepresent what the measure actually shows.”
StayAI interview agent, build of 20 October 2026, on the EARTHwise agent foundation. First chat checks, answer verbatim. Reviewed with the creator of the Stay Interview method.
You bring
-
Managers and their teams
The managers who will hold the stay interviews, the teams they lead, and a named sponsor in HR or the business.
-
About four to five weeks
A baseline Index reading, the interviews themselves, and a second reading at the close.
You keep
-
Stay plans that get done
Every interview briefed, prompted and drafted with the agent, with actions tracked to completion.
-
Two KeenCorp Index readings
Team-level baseline and close, so you can see which units to act on next, and show the board what moved.
Paid, priced at cost. A scoped proposal follows a short intro call.
Way in 2 · Create your own pilot with us
Your use case, your agent, your team: a pilot scoped with you.
StayAI is the first application of the Human-Agentic Enterprise. The same platform can carry an agent of your own: in sales and pricing, IT operations, scheduling, customer service, or wherever an agent would take real responsibility. We scope it together, customise the agent for your organisation, and run it with the people whose work it joins.
1 · Scope
An intro call
You bring the use case, the team that will work with the agent, and a named sponsor. We agree what the agent will be responsible for and what a good result looks like, and send a scoped proposal.
2 · Customise
Your agent, tested and tuned
The agent is built with your governance, purpose, brand and regulatory context ingested, then tested and tuned in the EARTHwise Arena against thirteen criteria and your own, before it meets your team.
3 · Run
At work, with both sides visible
The agent works inside an NVIDIA OpenShell sandbox, supervised for drift. The KeenCorp Index gives a team-level baseline before it arrives and a second reading at the close, so change can be attributed.
You bring
-
An agent use case
A process or decision where an agent would carry real responsibility.
-
A team that will work with it
The managers or staff whose work the agent joins, and a named sponsor.
You keep
-
Your own customised agent
Your governance, purpose and context as agentic intelligence you can trust with real tasks, and decision intelligence that improves with it.
-
Before and after evidence
Benchmark scores against the bare model, two Index readings, and a replayable record, so the case is visible to your CFO as well as to HR and IT.
Paid, priced at cost. A scoped proposal follows a short intro call.
One platform
Human and agentic alignment, governed together in one dashboard.
The Human-Agentic Enterprise gives enterprises one integrated dashboard to govern human and agentic alignment together, as one system. It can be customised to any use case; the StayAI platform is its first application.
1 · Contained and secure
Customised agents
Built for your organisation, with your governance, purpose, brand and regulatory context ingested.
- Runs inside an NVIDIA OpenShell sandbox, with a harness around it
- Kept secure and up to date by our own security agents
- Patches applied automatically; major upgrades wait for a human
2 · Aligned decision logic
Agentic alignment
Tested under pressure on thirteen criteria, tuned to win-win and long-horizon decision logic, benchmarked against the bare model.
- The alignment memory carries forward
- Supervised for drift once the agent is at work
- Every run logged, replayable and exportable
3 · Healthy teams
KeenCorp Index
Live readings of tension and alignment at team level, from written communication that already exists.
- No surveys, no biometrics, no individual records
- Groups of at least ten people, never individuals
- A baseline before agents arrive, so change can be attributed
Trusted agents and healthy teams, working together as a thriving organisation.