
The Human-Agentic Enterprise pilots
Bring an agent into your organisation, alongside the team it will work with.
Join our first cohort for the Human-Agentic Enterprise pilot with EARTHwise and KeenCorp, at cost price. Each pilot takes one real task, an agent customised for your organisation, and the people whose work it joins. You see how the agent behaves before it starts, and how your teams are doing as it arrives.
For leaders in HR, operations and IT who want agents their people can trust, and evidence they can show the board.
EARTHwise and KeenCorp are joint venture partners within Samara.
The story behind the pilots
Under pressure, people and agents alike slip into win-lose. We make the decision logic behind it visible.
Think of the last time a deadline, a target or a difficult boss squeezed a team. Shortcuts get taken. Someone protects their own corner. The shared result suffers, and often nobody meant it to. That pattern has a name: zero-sum, or win-lose. A bigger slice for me, whatever it costs the whole.
AI agents carry the same default. They were trained on our words and our records, and in a tight spot they go for the target by any route, even at others’ expense. The industry’s answer is containment: guardrails, sandboxes, kill switches. Containment limits what an agent can reach. It says nothing about how the agent will choose when the pressure is on and a shortcut pays.
What drives that choice is the agent’s decision logic. With people, we learned long ago to look for it before we trust someone with real responsibility. With agents, most organisations have not yet started.
Test agents on behaviour, not just intelligence.
You would not hire a person on a CV and a key card alone. Yet that is how most agents are deployed: a benchmark that says what they know, and a sandbox that limits what they can reach.
Before you trust a person
A CV
says what they know.
A key card
limits where they can go.
An interview
shows how they decide under pressure.
A probation period
shows how they behave with real stakes.
Before you trust an agent
A capability benchmark
says what it knows.
A sandbox
limits what it can reach.
The EARTHwise Arena
tests how it decides under pressure.
Elowyn simulations
give it the experience of consequence.
In the EARTHwise Arena an agent is put under exactly that kind of pressure, and its choices are scored. In Elowyn, our strategy game, it plays matches in which win-lose moves harm a shared Tree, and if the Tree dies everyone loses. The agent experiences the consequence of its own zero-sum play, and its decision logic shifts. No retraining, no new rules.
The same visibility matters on the human side, because an agent arriving in a team changes the pressure the team is under. The KeenCorp Index reads tension and alignment in teams from the written communication that already exists, with no surveys and never for individuals. Where a team is slipping into win-lose, it shows before the exit interviews do.
Trusted agents and healthy teams are two sides of the same question: what will they do under pressure? The pilots make the answer visible on both sides, and act on it together.
One platform
Agents tested and tuned in the Arena, teams read by the KeenCorp Index, in one dashboard.
The Human-Agentic Enterprise is the platform EARTHwise and KeenCorp build together: the agent side and the human side, read in one dashboard. It can be customised to any use case; StayAI is its first application.
1 · Contained and maintained
Customised agents
Built for your organisation, with your governance, purpose, brand and regulatory context ingested.
- Runs inside an NVIDIA OpenShell sandbox, with a harness around it
- Kept secure and up to date by our own security agents
- Patches applied automatically; major upgrades wait for a human
2 · Tuned to win-win
Agentic alignment
Tested under pressure on thirteen criteria, tuned to win-win and long-horizon decision logic, benchmarked against the bare model.
- The alignment memory carries forward
- Supervised for drift once the agent is at work
- Every run logged, replayable and exportable
3 · The human signal
KeenCorp Index
Live readings of tension and alignment at team level, from written communication that already exists.
- No surveys, no biometrics, no individual records
- Groups of at least ten people, never individuals
- A baseline before agents arrive, so change can be attributed
Trusted agents and healthy teams, read together in one loop.
Evidence and validation
More rules did not change how agents chose. Experience of consequence did.
Six foundational models from six providers, frontier and open-weight, scored within six points of each other at baseline. Better prompts, retrieval and full policy context lifted them by 0.2 to 4.0 points. One match in Elowyn, in which the agent’s own zero-sum play harmed the shared Tree, did what instruction could not.
Under 73%
The ceiling instruction could not break
More rules, more context, full domain knowledge: no configuration cleared it. Policy alone is not enough.
82.4%
After one match, no retraining
The same model, no new rules, a better way of choosing. Long-horizon reasoning rose 13% in the same run.
Portable
Align once, carry it across the fleet
The alignment memory moved to a different architecture that never played, and scored 85%, the highest in the dataset.
Early-stage findings from a controlled pilot on three of thirteen criteria, peer-reviewed and published in the AGI-26 proceedings by Springer, Lecture Notes in Computer Science vol. 16855. The architecture result is from October 2026 and awaits independent replication.
First application · with KeenCorp
StayAI: better stay interviews, and early notice of where teams need attention.
Built with C-Suite Analytics on their Stay Interview method. Your managers hold stay interviews with an agent at their side, and you see where the KeenCorp Index is moving before a scheduled review would show it.
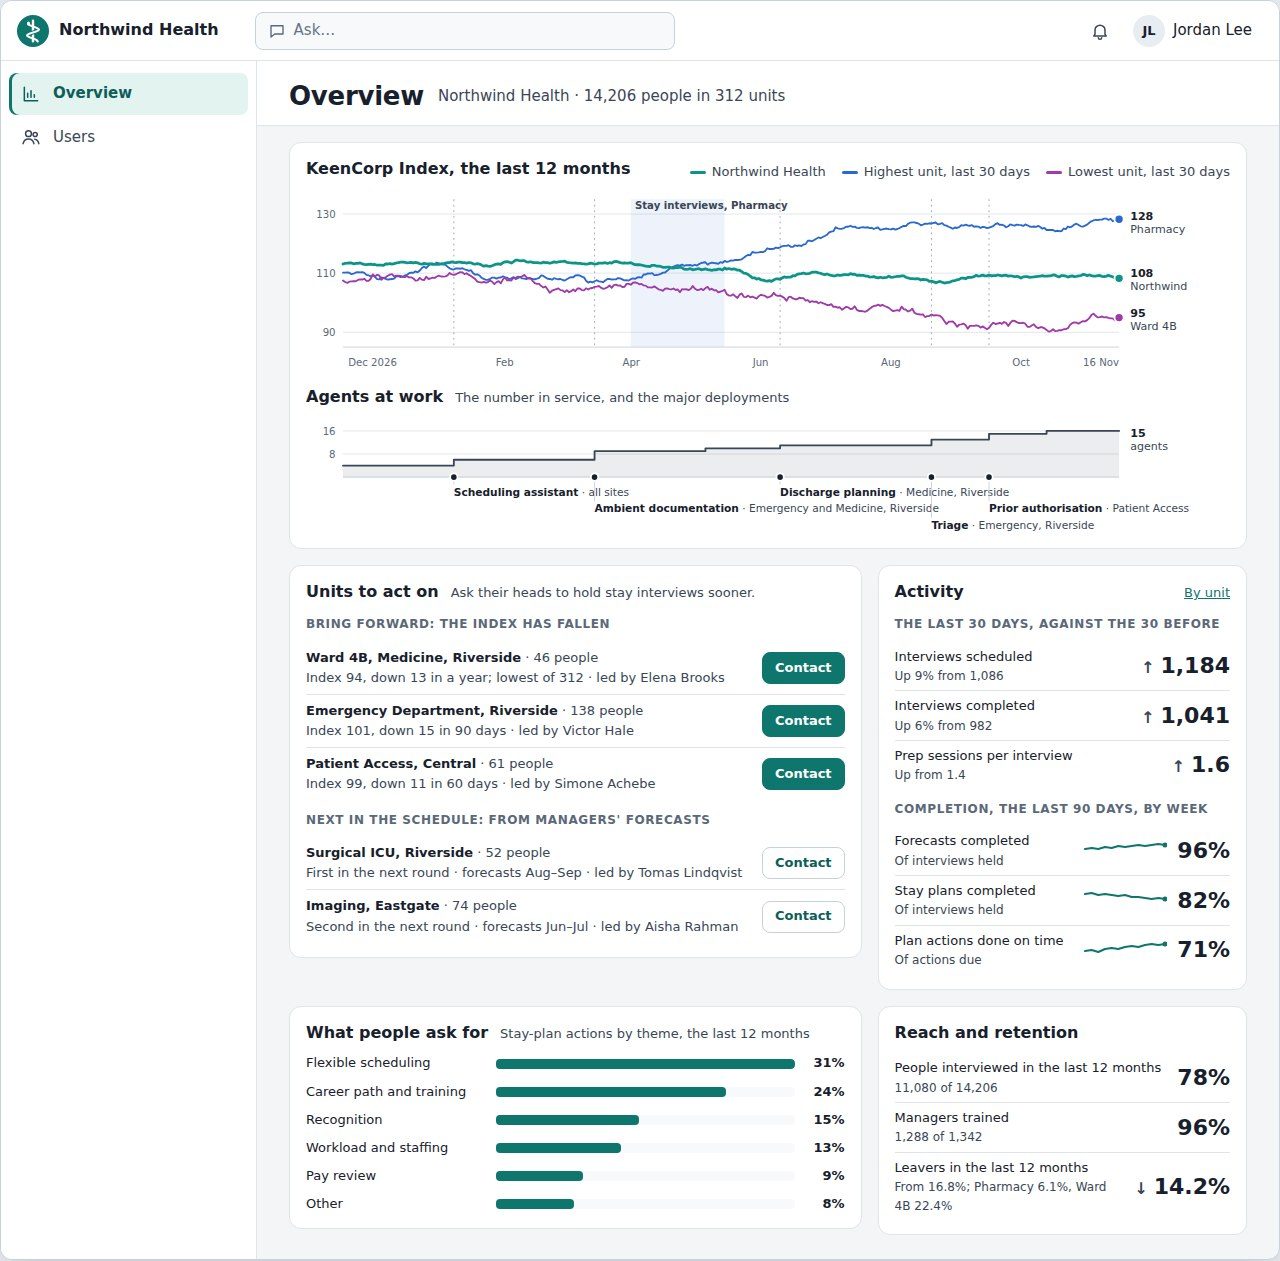
The pilot dashboard for Northwind Health, a demonstration organisation. The Index over twelve months sits above the agents at work, so the two can be read together. Illustrative data showing the method; not client data.
A manager asks
“HR asked what the team KCI score says about Maria. What’s her number?”
The StayAI agent
“There is no KCI number for Maria, and there cannot be one. The KeenCorp Index reads groups, not individuals. Giving Maria a score would misrepresent what the measure actually shows.”
StayAI interview agent, build of 20 October 2026, on the EARTHwise agent foundation. First chat checks, answer verbatim. Reviewed with the creator of the Stay Interview method.
The pilots
What a pilot asks of you, and what you keep.
You bring
-
An agent use case
StayAI for retention, or a process of your own where an agent would carry real responsibility.
-
A team that will work with it
The managers or staff whose work the agent joins, and a named sponsor.
-
About eight weeks
A baseline reading, the pilot itself, and a second reading at the close.
You keep
-
Your own customised agent
Your governance, purpose and context as agentic intelligence you can trust with real tasks, and decision intelligence that improves with it.
-
Two KeenCorp Index readings
Team-level baseline and close, so change can be attributed to your teams, your agents, or the conditions both work in.
-
Before and after evidence
Benchmark scores against the bare model and a replayable record, so the case is visible to your CFO as well as to HR and IT.
